How to Use Hash Lab: Watch, Compare and Verify Hashes in Your Browser
Hash Lab is a free in-browser workbench for hash functions. This guide shows how to watch the avalanche effect, time SHA-256 against Argon2id, read stored hash strings and verify files and webhooks.
Hash Lab is a free, in-browser workbench for cryptographic hash functions. You type an input and watch SHA-256, SHA-3, BLAKE3, Argon2id, bcrypt and others hash it live, side by side, with timings. Nothing you type leaves the browser tab. It is built for one job: letting you see how hashing behaves, and verify a hash, before you trust a library or a blog post about it.
This is a hands-on guide, not another algorithm comparison. If you need the decision itself, I cover that in the complete guide to password hashing. What follows is how to use the lab to understand that decision and check your own work.
Why run hashes yourself instead of reading about them
Most hashing mistakes I see in identity systems are not exotic. They are a fast hash used where a slow one belonged, a cost factor nobody has revisited in years, or a stored hash string nobody on the team can read. Each of those is easier to catch when you have watched the functions run.
The standards are clear on the big point. The OWASP Password Storage Cheat Sheet says plainly that fast hashing algorithms such as SHA-256 are not suitable for password storage. It recommends Argon2id with a minimum of 19 MiB of memory, an iteration count of 2, and a parallelism of 1. NIST SP 800-63B requires that passwords be salted and hashed with a suitable password hashing scheme, with a salt of at least 32 bits. It adds that the cost factor should be as high as practical and should rise over time.
Reading those sentences is one thing. Watching a SHA-256 hash finish in a hundredth of a millisecond while Argon2id takes about 80 milliseconds on the same machine is what makes "as high as practical" concrete. That is the gap Hash Lab is designed to show.
What is in the lab
Hash Lab has six interactive tools and a reference catalog:
- Properties demo: hash any text with one algorithm and switch output between hex, Base64, Base64URL and Base32.
- Algorithm compare: run every general-purpose hash on the same input, with bit length, year, security status and average time.
- Password hashing: Argon2id, bcrypt and scrypt with sliders for every cost parameter.
- Hash identifier: paste an unknown hash and get the likely algorithm, with a confidence level.
- File hash: stream-hash a local file and compare it against a publisher's reference value.
- HMAC signing: compute HMAC-SHA256, SHA-384 or SHA-512 signatures, the construction most webhook providers use.
The algorithm index has a page per function with its designers, year, known attacks and a modern alternative where one applies. Every tool links into it, so you can move from "what did I just see" to "why" in one click.
Walkthrough 1: watch the avalanche effect
Start with the property that makes a cryptographic hash useful at all. Change the input slightly, and the output should change completely.
- Open the properties demo and leave the algorithm on SHA-256.
- Type a harmless sample such as correct-horse-battery-staple. Note the output.
- Change one character. I changed the final "e" to "f".
- Compare the two outputs.
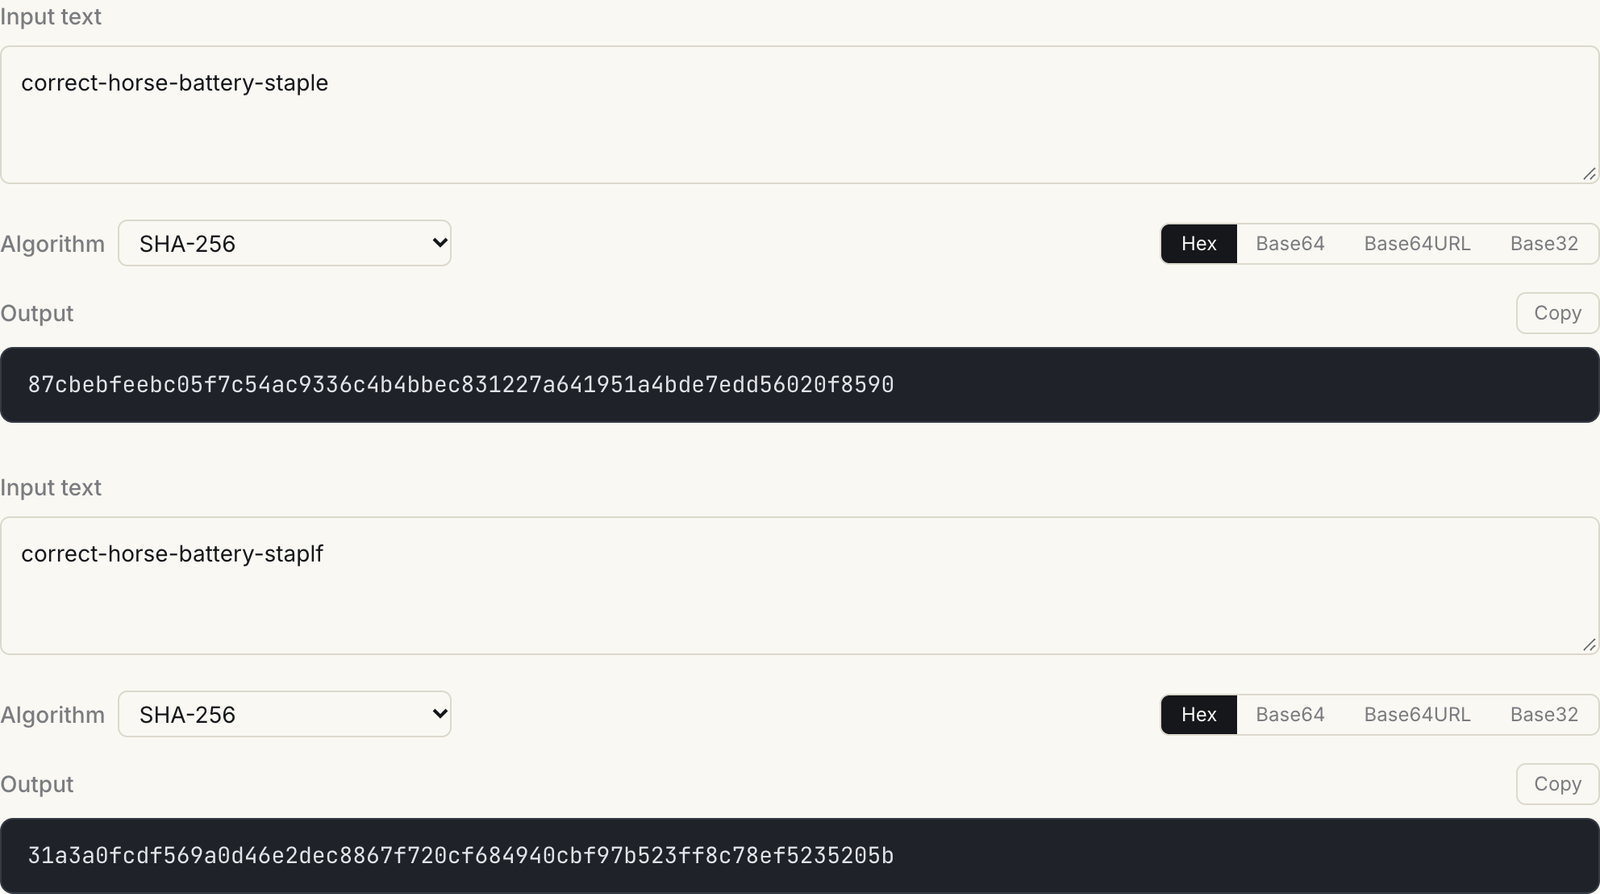
I counted the differing bits between those two outputs: 125 of 256, close to the half you expect from a well-behaved hash. There is no "nearly matching" hash. That is why you cannot guess your way toward an input by watching outputs get warmer.
Two more things worth trying here. Hash the same text twice and confirm the output is identical, which is determinism. Then paste a full paragraph and confirm SHA-256 still returns 64 hex characters, which is fixed-length output. Switching the format toggle to Base64 is a quick way to see that the bytes are the same and only the encoding changed. Mismatched encodings are behind a large share of "the hashes don't match" bug reports.
Walkthrough 2: put a fast hash next to a password hash
This is the exercise I would hand to any engineer about to write a login flow.
First, open Algorithm compare with the same sample input. The lab hashes it with every general-purpose function, 50 times each, and shows the average.
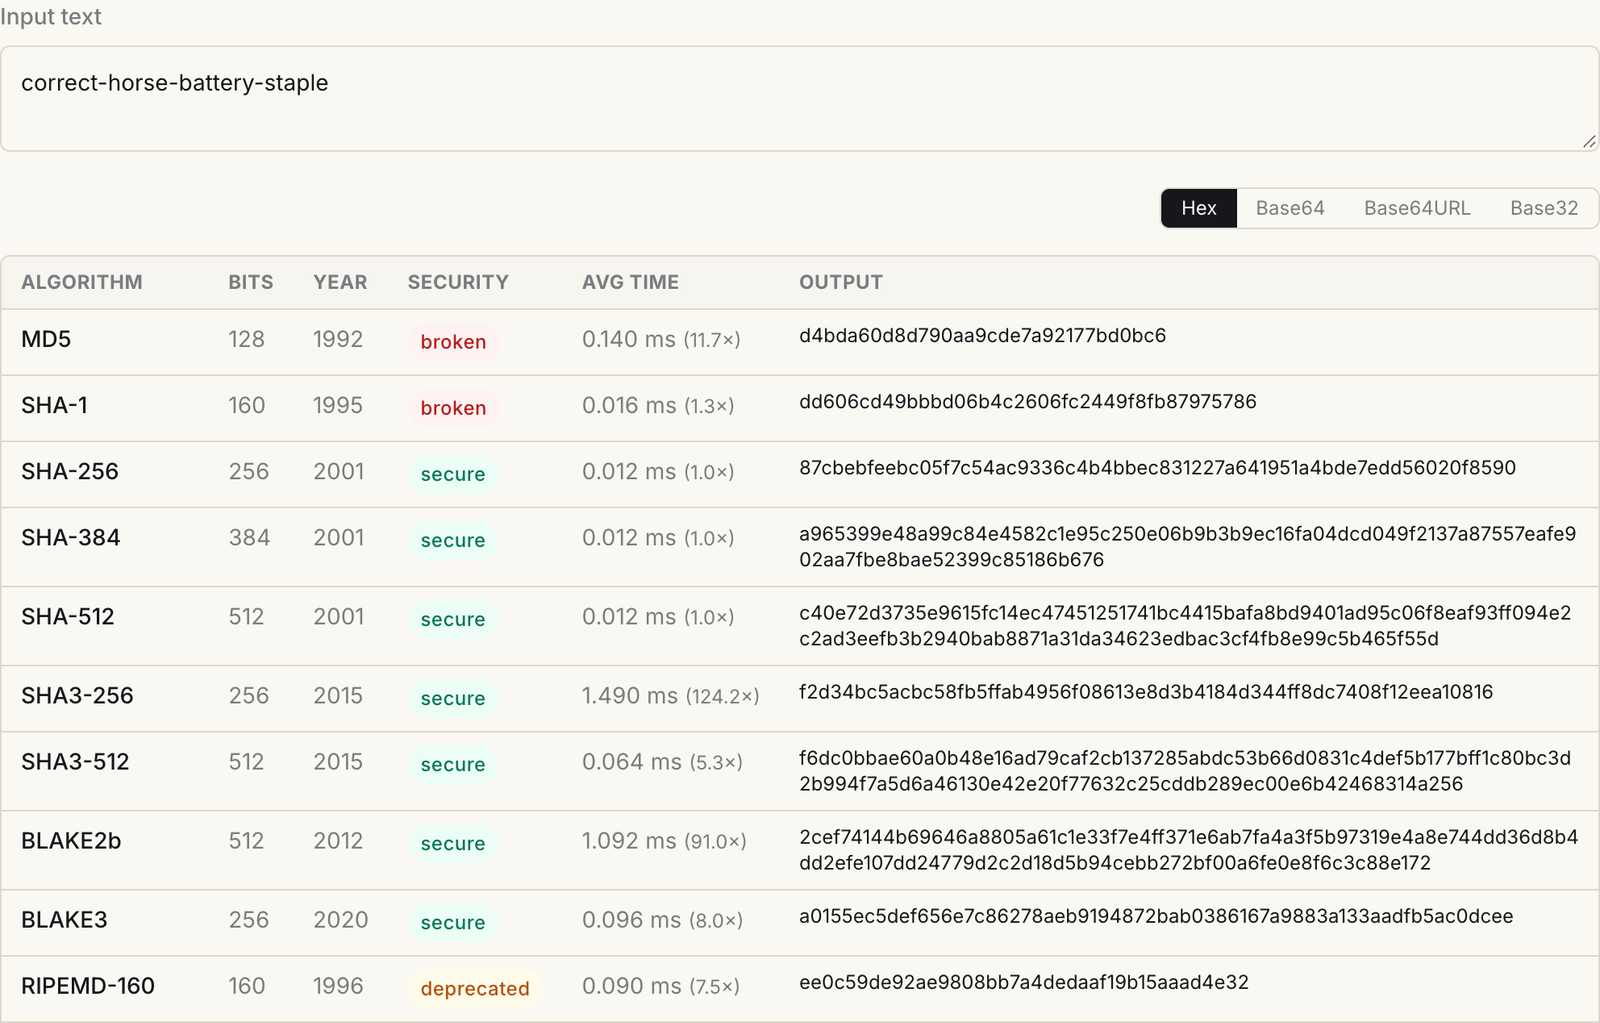
SHA-256 averaged 0.012 ms per hash in my browser. The table also shows MD5 and SHA-1 labelled broken. For SHA-1 that is not theoretical: the SHAttered team (CWI Amsterdam and Google) published the first real SHA-1 collision in February 2017, two different PDFs with the same hash. NIST announced in December 2022 that SHA-1 should be phased out by December 31, 2030.
Now open Password hashing, keep Argon2id selected, and leave the defaults: 2 iterations, 19 MiB of memory, parallelism 1. Those match the OWASP minimum. Press "Hash password".
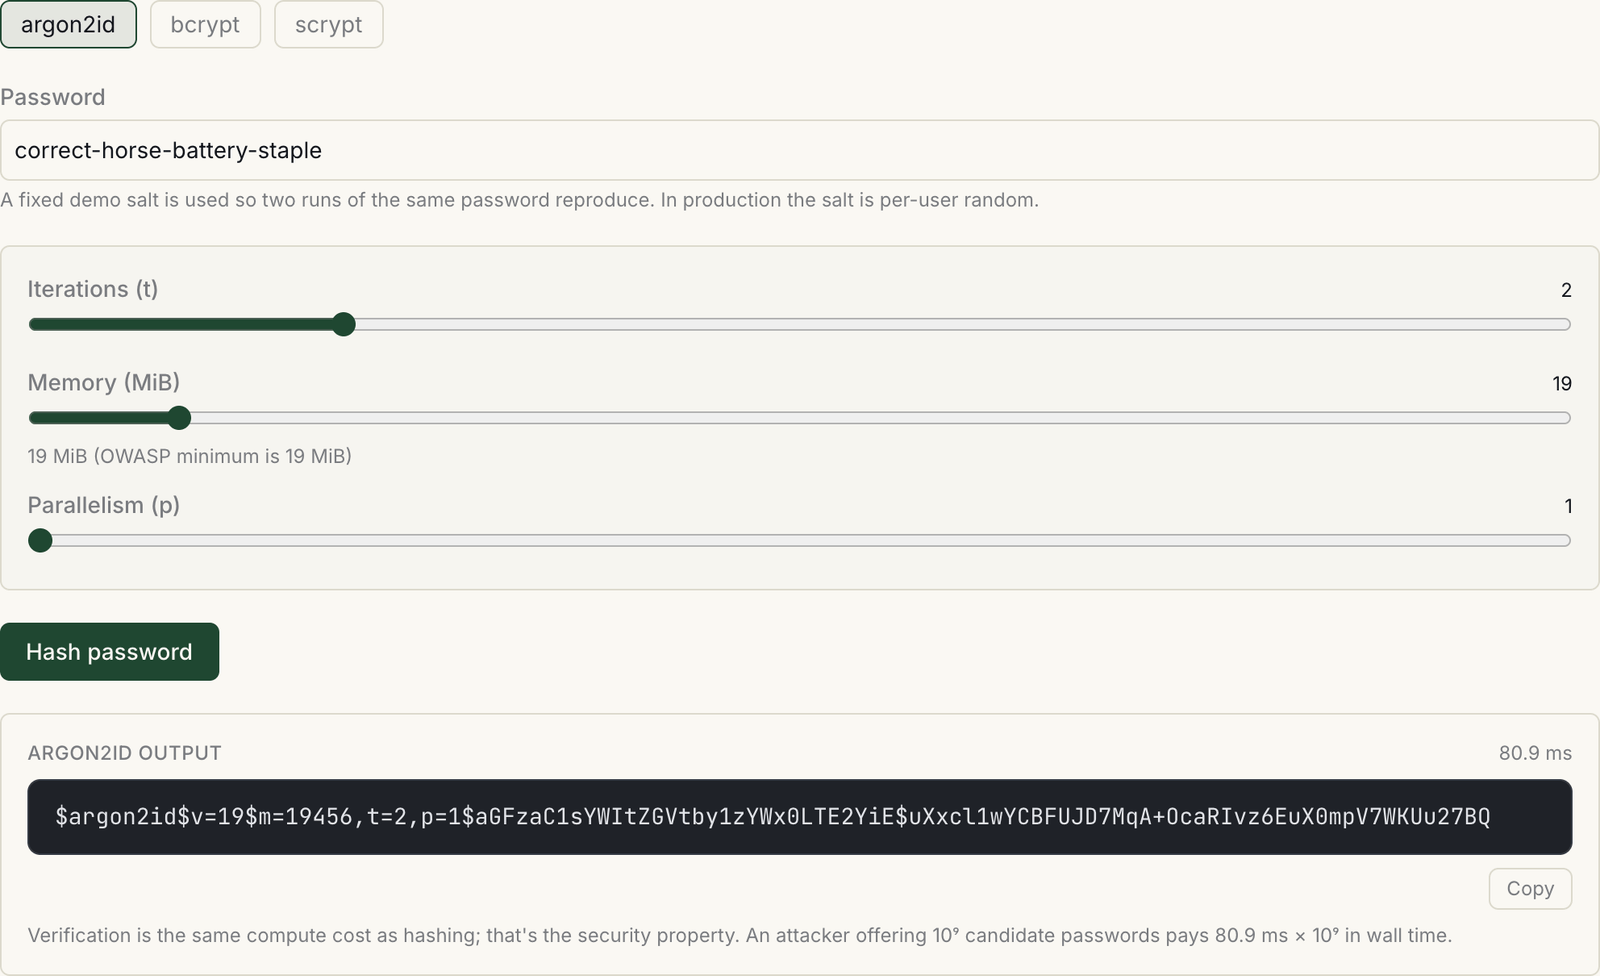
On the same machine, Argon2id took 80.9 ms. That is roughly 6,700 times slower than SHA-256. The lab spells out what that means for an attacker. A billion guesses at 0.012 ms each is about 3.3 hours of single-core work. A billion guesses at 80.9 ms each is about 2.6 years. Memory hardness makes the gap wider on attacker hardware, because every parallel guess also needs its own 19 MiB.
Then play with the sliders. Raise memory to 64 MiB and watch the time climb. Switch to bcrypt and move the cost factor from 10 to 12; each step doubles the work, and cost 12 took about 334 ms in that same browser session. Switch to scrypt and watch the memory estimate under the N slider. None of these numbers are your production numbers. The point is to feel the trade-off before you pick a value.
Walkthrough 3: read a stored hash string
Look again at the Argon2id output above. It is not just a hash. It is a record of how the hash was made:
- $argon2id names the variant.
- v=19 is the algorithm version (0x13).
- m=19456,t=2,p=1 are memory in KiB, iterations and parallelism.
- The next field is the salt, then the hash itself, both Base64 encoded.
That encoding is why you can raise parameters later without breaking existing users. Each stored hash carries its own settings, so you verify old hashes with old settings and rehash at the next successful login. A bcrypt string works the same way: $2a$12$ tells you the cost is 12.
When you inherit a database and nobody knows what is in the password column, paste one value into the hash identifier. Use a test account's hash, never a real user's.
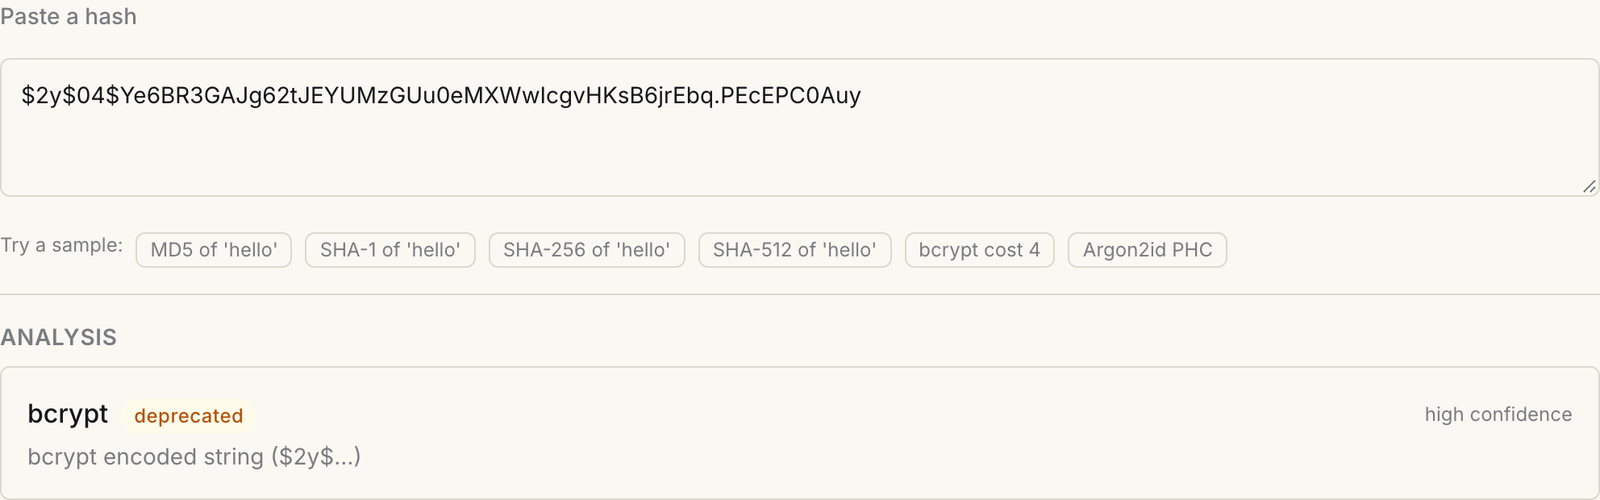
Encoded formats like bcrypt, Argon2 and scrypt are identified with high confidence because their prefixes are unambiguous. A bare 64-character hex string is different. Several algorithms produce 32 bytes, so the identifier shows every candidate at medium confidence rather than pretending to know. If your password column is bare hex, that alone tells you it is probably a fast hash and needs a migration plan.
Walkthrough 4: verify a download or a webhook
Hashing is not only for passwords. Two everyday verification jobs live in the lab.
For a downloaded installer or ISO, open File hash, choose the algorithm the publisher used (usually SHA-256), drop the file in, and paste the publisher's reference value into the compare box. The file is streamed through the hash in chunks inside your browser and never uploaded. The lab tells you whether the values match. If they do not, either the file changed or you picked the wrong algorithm or format. My longer guide to implementing checksums and hash verification covers how to automate this in a pipeline.
For webhooks, open HMAC signing. Enter a test key and a sample payload, and you get the signature your receiver should compute. Change one character of the key and the signature changes completely, which is the property that lets a receiver reject forged requests. It is a fast way to debug a signature mismatch: compute the expected value by hand and compare it with what your code produced.
What Hash Lab cannot tell you
The lab is a learning and checking tool. Be clear about its limits before you lean on it.
- Browser timings are not server timings. The password demo runs WebAssembly in a browser tab. Your production servers, language runtime and load will differ. OWASP's own advice is to benchmark chosen parameters on the target system, and that still applies.
- Compare timings are noisy. They are averages over 50 hashes and include library loading on the first pass. Some rows can look oddly slow on the first run. Treat them as relative, and re-run before drawing conclusions.
- The password demo uses a fixed salt. That makes runs reproducible for learning. In production every user needs a unique random salt; RFC 9106 recommends 16 bytes for password hashing.
- The demo sliders are capped. bcrypt stops at cost 12 and Argon2id at 128 MiB so the tab stays responsive. RFC 9106's second recommended Argon2id setting is 64 MiB with 3 iterations and 4 lanes, which fits. Its first recommendation uses 2 GiB, which does not.
- It does not include PBKDF2. If you need FIPS-validated hashing, OWASP recommends PBKDF2-HMAC-SHA256 at 600,000 iterations; benchmark that in your own stack.
- Identification is a guess. The identifier reads length, character set and prefixes. It cannot recompute anything, and it cannot tell SHA-256 from another 32-byte hash.
What to do with what you saw
Once you have watched the gap between fast and slow hashes, the next steps are short.
- Check what your system stores. If it is bare hex from MD5, SHA-1 or a single SHA-256 pass, plan a migration that rehashes at login.
- Pick the algorithm with a framework, not a hunch. The complete guide to password hashing opens with the four-bucket decision and then covers parameters in detail.
- Tune on your hardware. OWASP's general rule is that calculating a hash should take less than one second. Within that, go as high as your login volume allows.
- Revisit the cost factor on a schedule. NIST expects it to rise as hardware gets faster, and the encoded hash format lets you do that without a flag day.
For non-password hashing, such as checksums, content addressing or signatures, choosing the right hash algorithm covers which function fits which job. Then come back to Hash Lab and confirm the behaviour yourself.
FAQ
Does Hash Lab send my input anywhere?
No. Every computation, including file hashing, runs in your browser using Web Crypto and WebAssembly libraries. Even so, use sample values. There is no reason to paste a real password or a production secret into any web page.
Why is SHA-256 a bad choice for storing passwords if it is secure?
SHA-256 is secure as a general hash: no practical collisions are known. It is also built to be fast, and speed helps an attacker who has stolen your database and is guessing offline. OWASP says fast hashes such as SHA-256 are not suitable for password storage. Use a deliberately slow, salted function such as Argon2id.
Why does Hash Lab label bcrypt "deprecated"?
It is the lab's own label for new designs. bcrypt has a 72-byte input limit and no memory-hardness setting. OWASP lists bcrypt for legacy systems, with a work factor of at least 10. Existing bcrypt hashes are fine to keep verifying while you migrate.
What Argon2id settings should I start with?
OWASP's minimum is 19 MiB of memory, 2 iterations and a parallelism of 1, which is the lab's default. RFC 9106 recommends 2 GiB with 1 iteration and 4 lanes where memory allows, or 64 MiB with 3 iterations and 4 lanes otherwise. Benchmark on your own servers and go as high as your login latency allows.
Can I use the hash identifier to crack a hash?
No. It only reads the format and length to suggest which algorithm produced a value. It does not reverse anything, because a cryptographic hash cannot be reversed. It is meant for auditing your own systems.
More like this
All Identity & CIAM- Identity & CIAMThe Science of Password Protection: Understanding Hashing, Salting, and the Future of AuthenticationUncover the mechanics of password hashing and salting, and how these techniques are pivotal in defending against cyber threats.
- Scams & CybersecurityWhat is Password Hashing Algorithm?What are various password hashing algorithms, their pros and cons, and how can they protect users' accounts?
- Scams & CybersecurityIs PBKDF2 Deprecated? What Developers Should Use in 2026PBKDF2 is not deprecated, but it is no longer the recommended default for new systems. Here is the honest, practical answer for…
Get new Identity & CIAM writing
Enjoyed this? Subscribe and tell us what you read most. Identity & CIAM is already ticked for you. No tracking pixels, unsubscribe with one click.